Trusted by engineering teams at
 and more
Put Tomosu’s AI agents to work as you build, ship and run software. Turn reliability blind spots across your code, dependencies, infrastructure, AI agents and runtime. Get proactive code hardening recommendations with the Production Reliability Index (PRI) guiding what to fix first.
Read-only by default. No credit card. Your first PRI score in under five minutes. Evaluating for a team? Request Demo
Trusted by engineering teams at
and more
Every path produces the same PRI score and the same fixes. Start where it is cheapest for you, add the others when you want coverage from the editor to the merge queue.
Score the file you are editing, see reliability findings inline, accept fixes as you write. Free edition, no account needed to install.
Point Tomosu at a public or private GitHub repo at tomosu.ai/start and get a full PRI report with the top gaps ranked.
Every pull request gets a reliability review and a PRI delta before merge. Comments land in the PR, nothing leaves GitHub.
Add mcp.tomosu.ai/mcp to Claude Code or Claude Desktop and ask for a PRI score, a gap analysis or a fix without leaving the chat.
Hand Claude a PR URL and let the Tomosu MCP tools review the diff for reliability regressions before a human reviewer sees it.
Already on CodeRabbit? Plug the Tomosu MCP in so its reviews carry PRI findings and runtime context alongside code quality comments.
Tomosu reads the systems you already run and builds one live model of them. It works in two places, continuously: pre-merge, on every change your team and your AI agents write, and at runtime, on the software already in production. What production teaches becomes the next check before merge.
AI assistants and coding agents have removed the bottleneck on writing software. They have not removed the bottleneck on keeping it dependable. The gap shows up as outages, customer escalations and rework that lands on the same senior engineers every time.
Tomosu's agents run across pre-merge and runtime. They continuously build a live context graph, turning production signals of reliability weaknesses into code hardening recommendations.
Findings and fixes in the editor as code is written, then every PR scored across the seven PRI dimensions, with regressions flagged and a fix proposed before review.
Runtime signals are matched to known reliability patterns and anti-patterns. L1 and L2 incidents are resolved automatically, with an evidence trail for the rest.
Each escalation becomes a new check upstream. The harness gets stricter where you actually fail, not where a generic rule set says you might.
Tomosu enters through reliability and security, the two failure classes that reach customers fastest, and reads the whole system rather than the diff alone.
Error handling, retries, timeouts, resource leaks, concurrency and the shortcuts AI assistants take.
Vulnerable, abandoned or behavior-changing packages, pinned against what your runtime actually loads.
IaC and config drift that removes redundancy, limits or alerts without anyone noticing.
Latency, saturation and error patterns matched to known anti-patterns and to your own incident history.
Every change scored before merge, with the PRI delta and the fix, in GitHub, in Claude or through CodeRabbit.
Tool contracts, context handling, planning and termination, cost budgets and prompt-injection exposure in the agents your software runs, scored as the Agent Reliability sub-index of the PRI.
PRI rolls seven reliability dimensions into a single trendable score, informed by runtime context and by the reliability patterns and anti-patterns in your code. The CTO tracks it, SRE moves it, Support feels it.
Reliability regressions caught at the PR instead of in the incident review. Fewer tickets bounce back to the team that wrote the feature.
L1 and L2 incidents resolved by agents with root cause, likely fix and evidence attached. Senior engineers paged for what only they can solve.
Customer-facing issues traced to the change that caused them. Support closes more without opening an engineering ticket.
Estimates for mid-size SaaS teams with 50 to 300 engineers and meaningful AI-assisted PR volume. Actual results depend on baseline metrics and adoption of recommended fixes. Model your own numbers →
Read-only by default. Enforcement stays under your control. Every decision is logged with evidence, ready for SOC 2, ISO or internal AI-use policy review.
No. Review tools comment on a diff. Tomosu scores the reliability of the whole system, flags or blocks changes that would lower it, resolves the incidents that slip through, and feeds what it learns back into the next review. Code review is one of six places you can meet it.
Read access to the repos you choose, and optionally your observability and incident tools for runtime context. Nothing is written to your repos unless you accept a fix. Enforcement, such as blocking a merge, is off until you turn it on.
Seven dimensions, each scored from code, dependency, infrastructure and runtime evidence, weighted by what has actually caused incidents in systems like yours. The score is trendable over time and comparable across services.
Every finding carries the evidence it was based on. Dismiss it and the harness learns from the dismissal. Fixes are proposals until a human accepts them. Merge gates start advisory and only become blocking when you promote them.
Yes. The VS Code plugin, the repo scan at tomosu.ai/start and the MCP server are free to start. Request Demo when you want the GitHub App on an organization or runtime integration.
All 22 questions, answered in full, on the FAQ page →
Scan a repo in five minutes. Install the GitHub App when you want every PR covered.
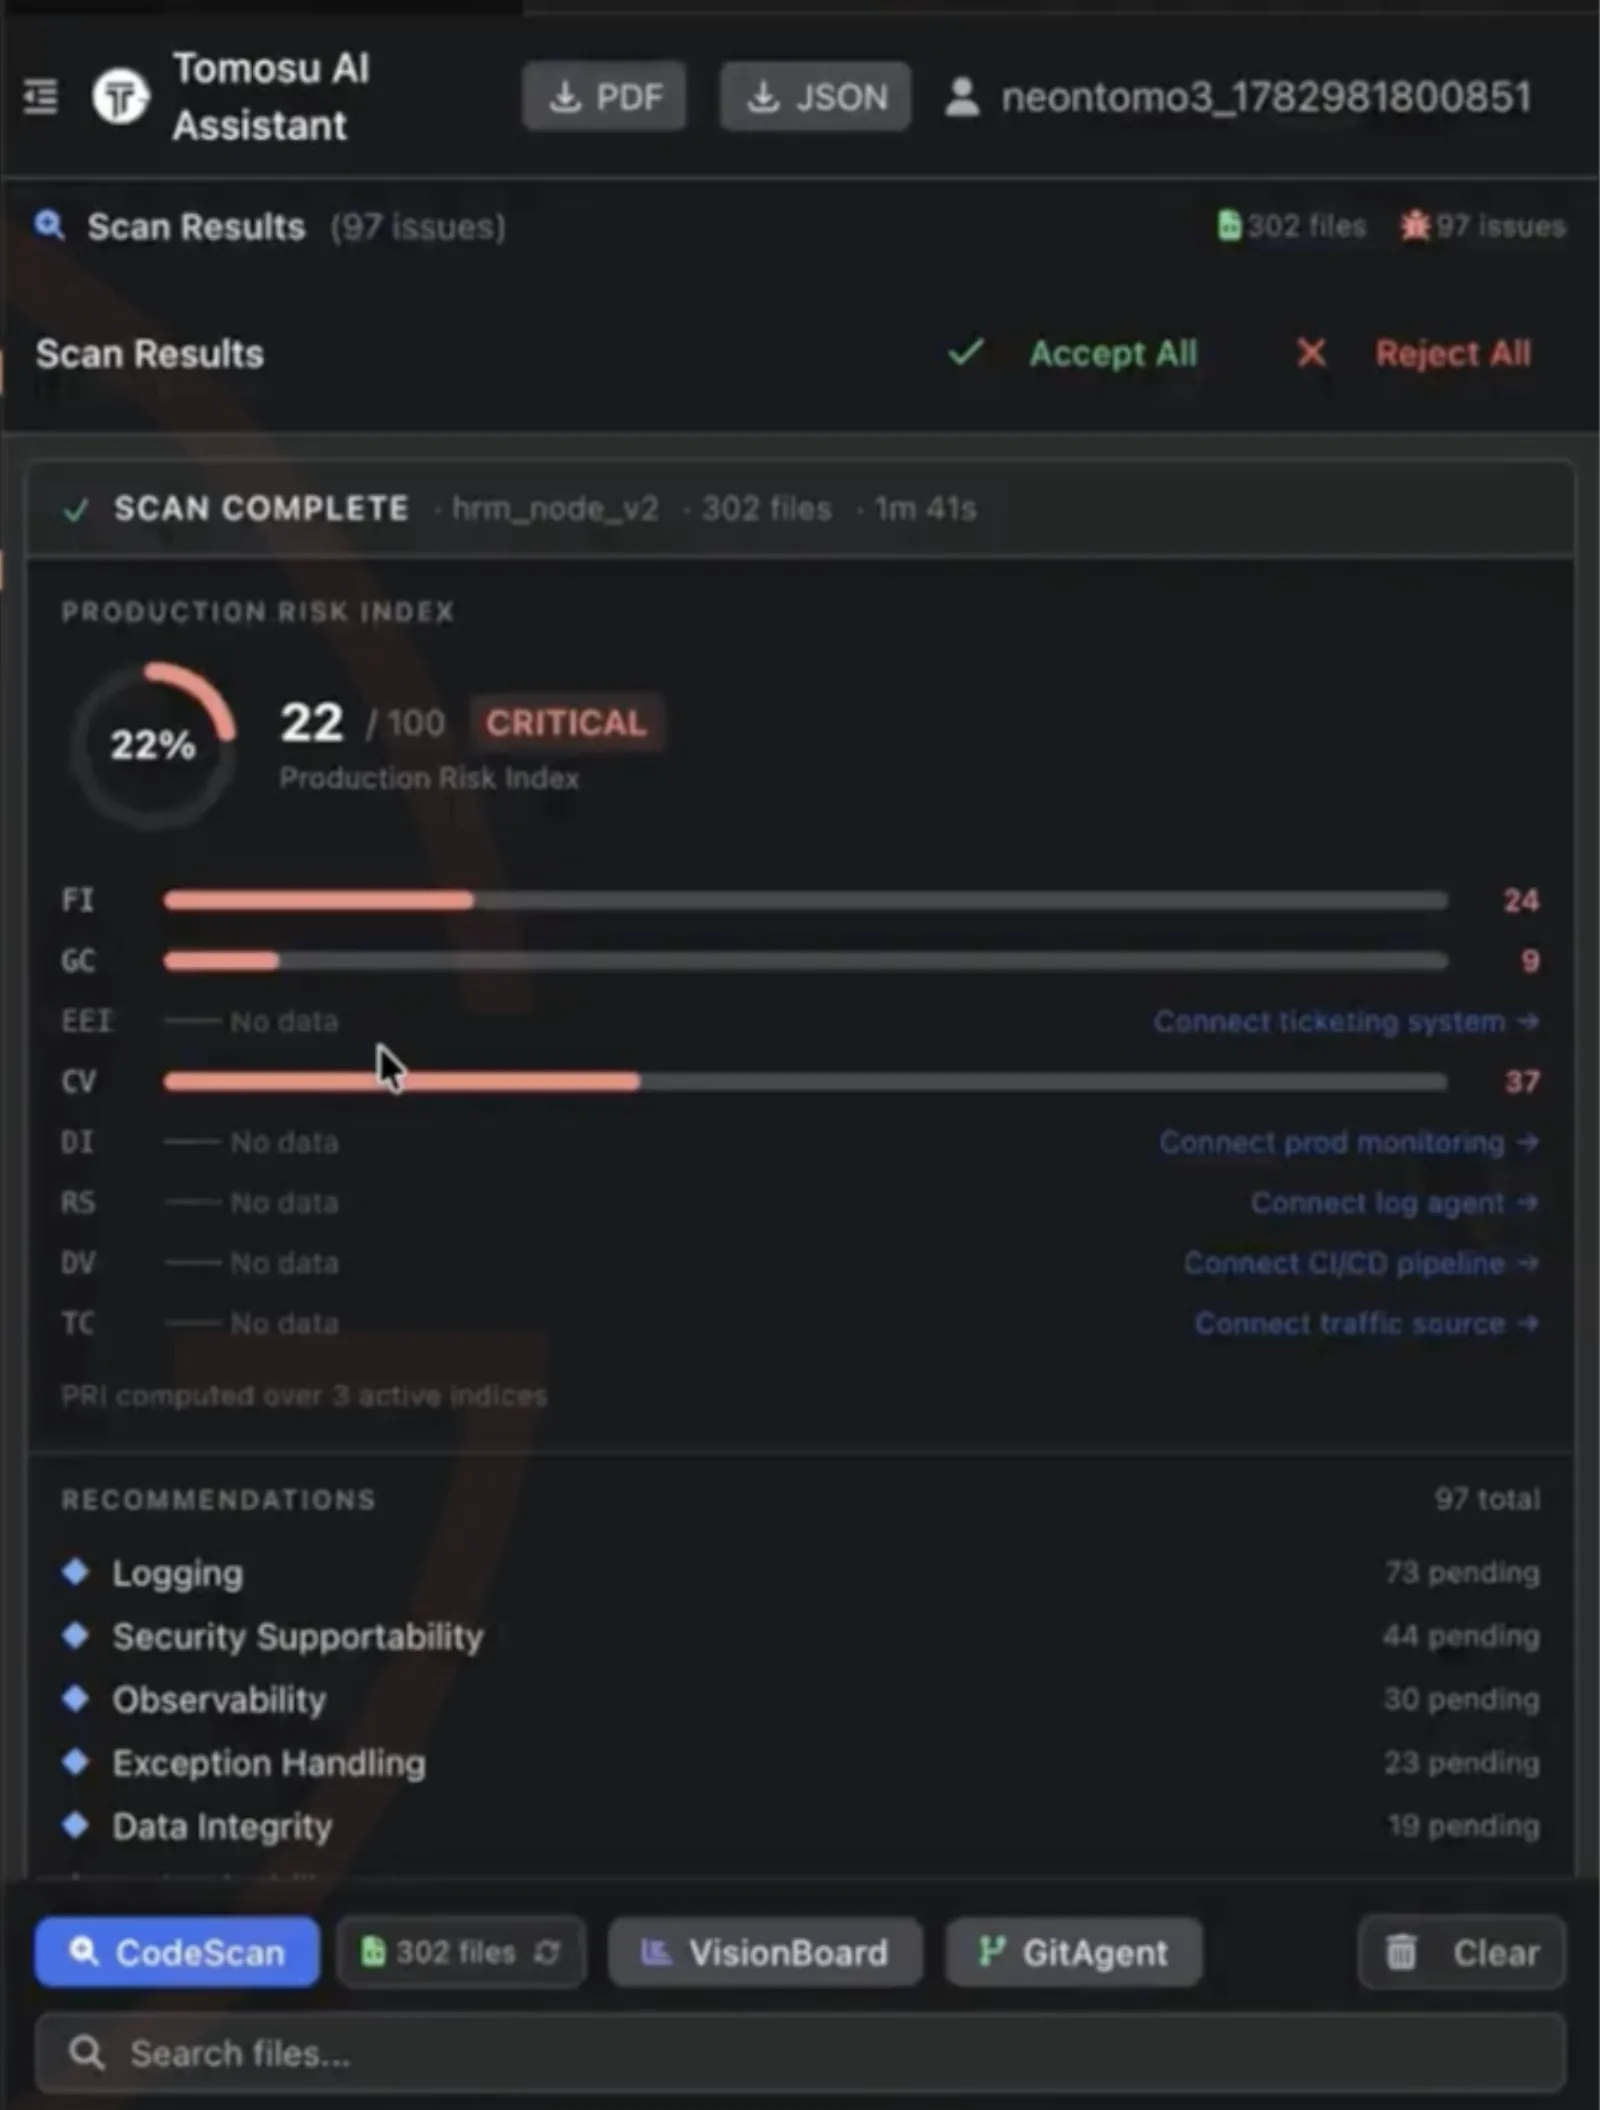
One scan of 302 files finds 97 reliability weaknesses and scores the repo 22 out of 100. Nothing has broken in production yet. This is the list of things that would.
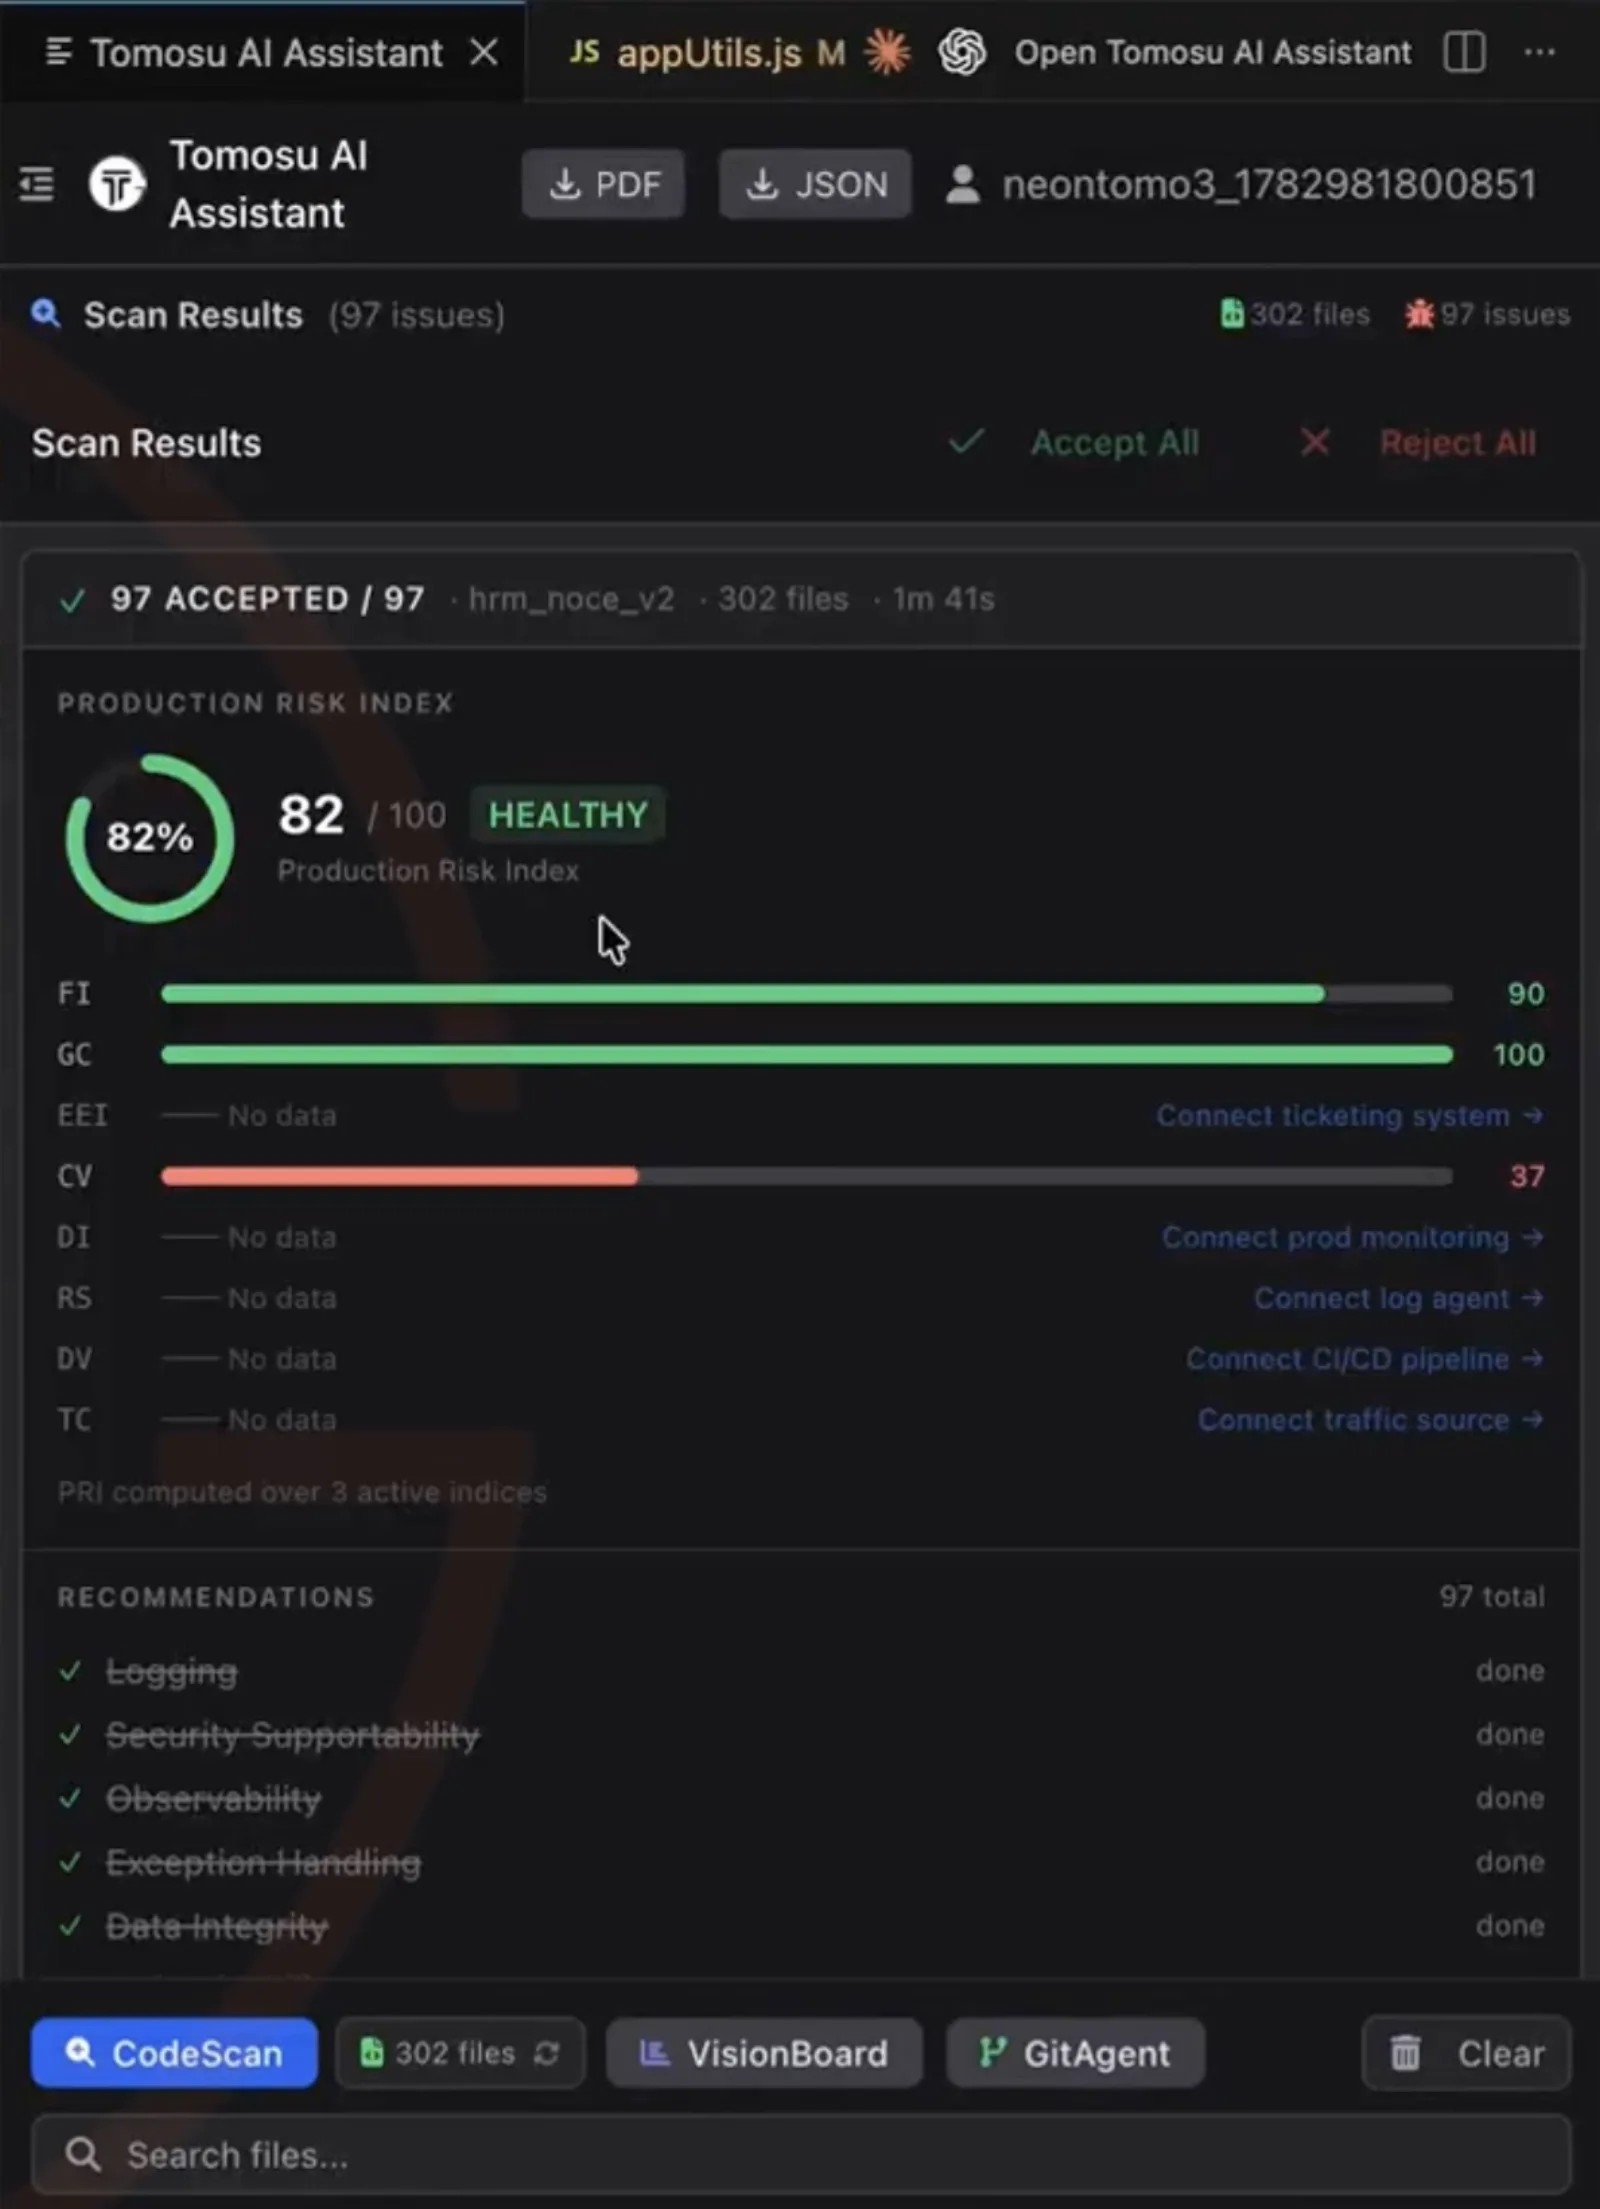
Accept them in the editor and the score moves before the branch reaches review. Logging, exception handling, observability, data integrity: done, as reviewable diffs a human approved.
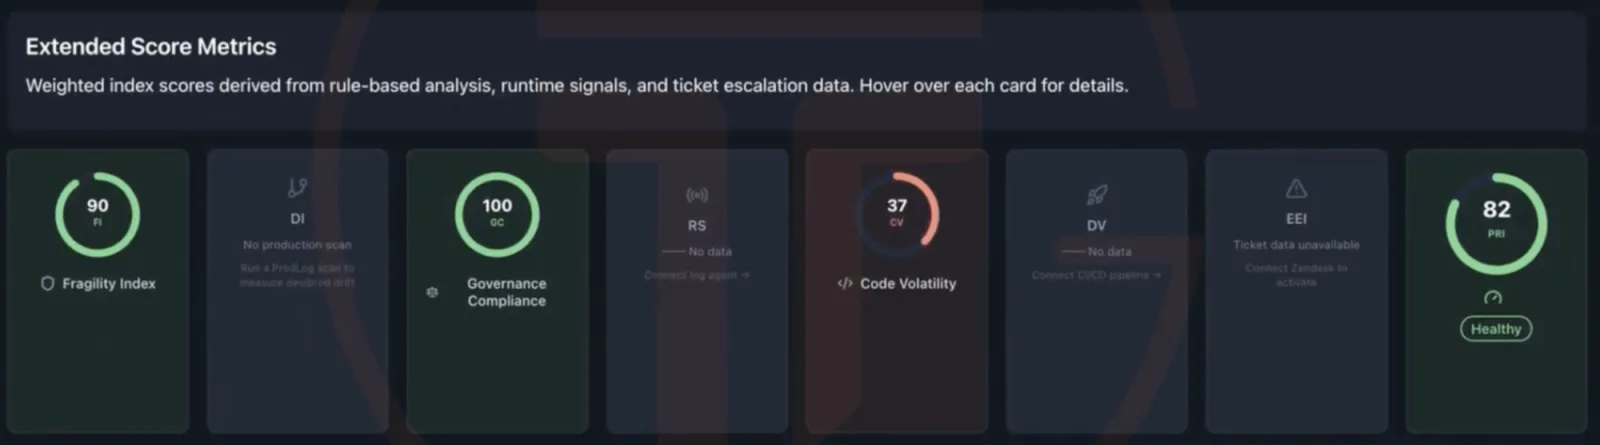
No separate reporting, no translation layer. What the engineer saw in VS Code is what the Visionboard shows the team, broken into the indices that produced it.
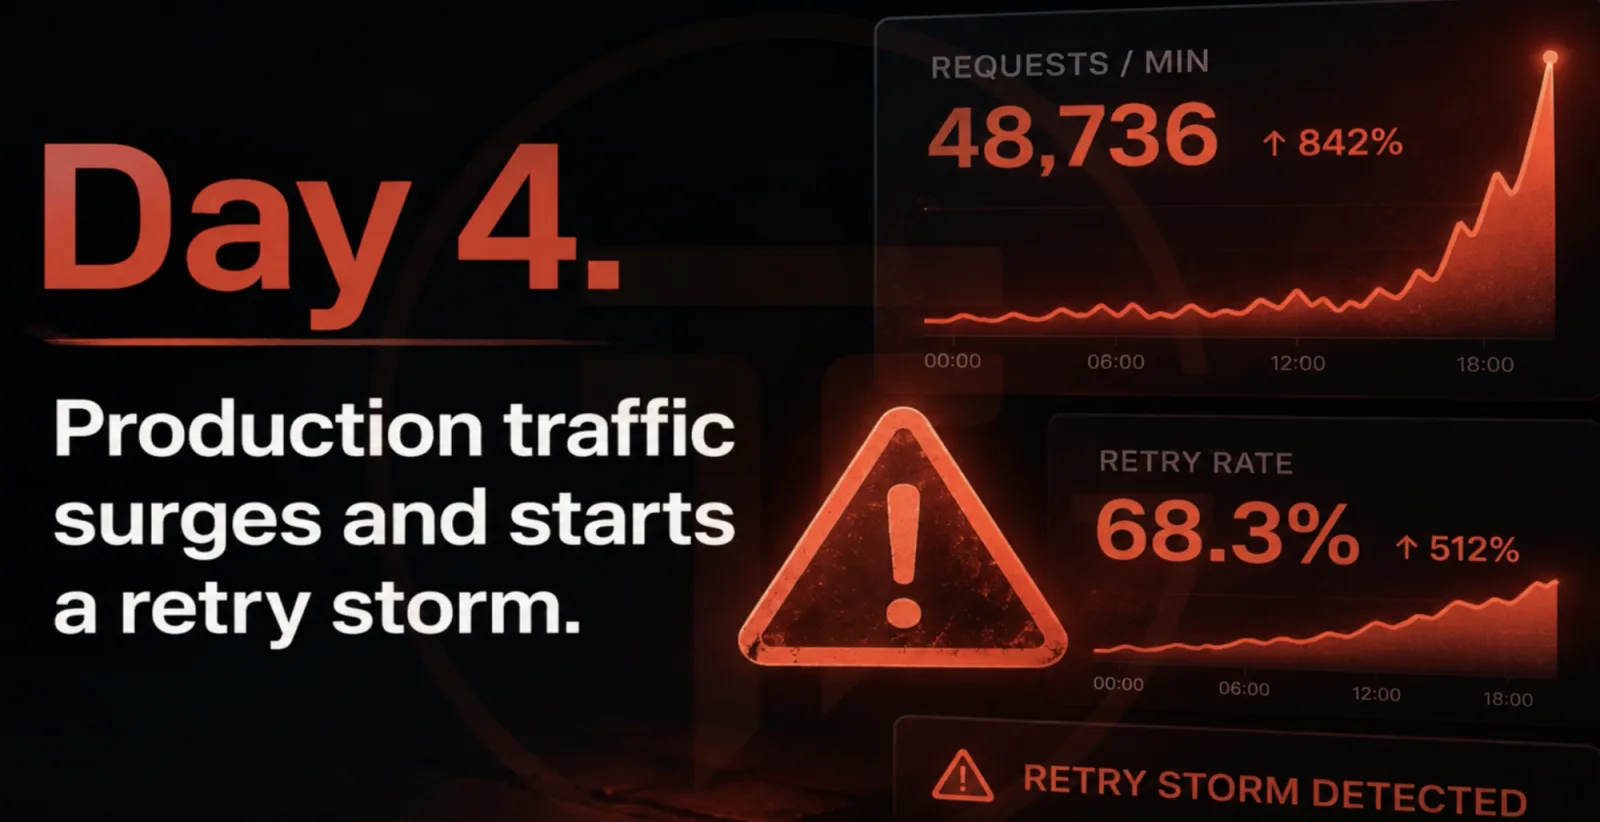
Traffic surges. A retry path without backoff amplifies it into a retry storm. This is the failure class no pre-merge suite reproduces, because it needs real load to exist.
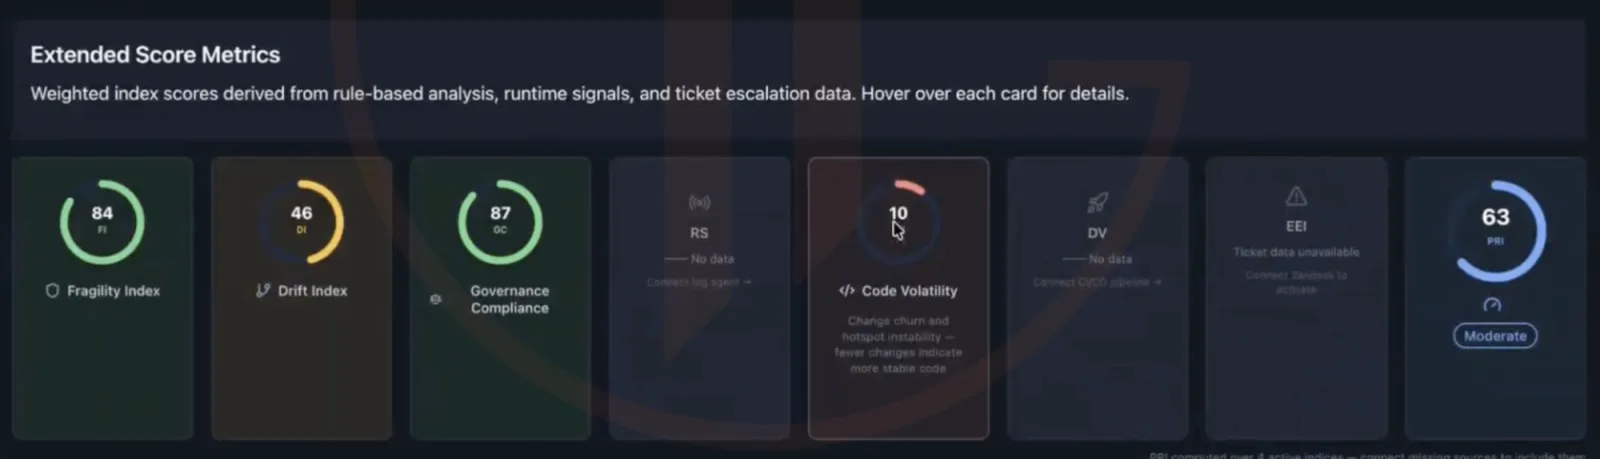
Runtime signals feed straight back into the score. PRI 82 → 63, and a Drift Index appears at 46: the gap between what you shipped and what production is actually doing.
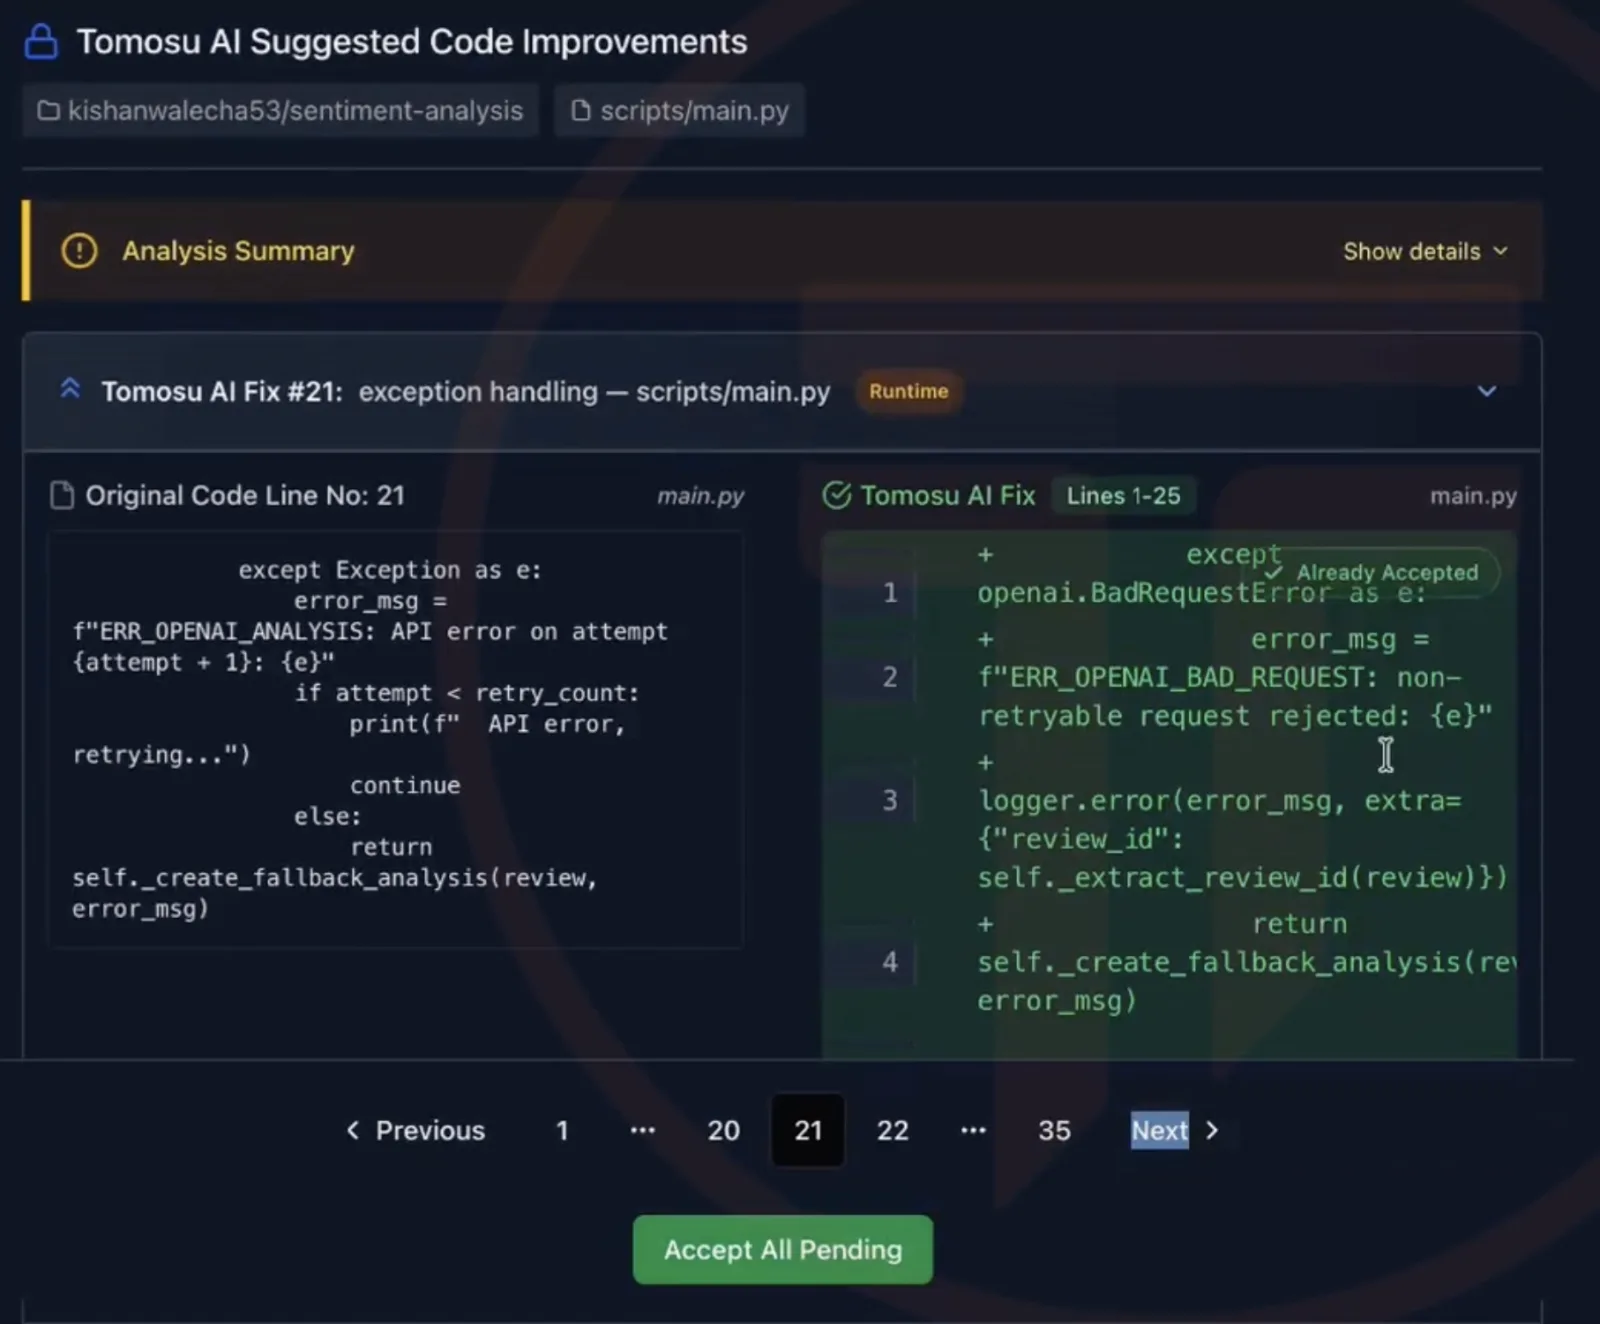
Root cause traced to the retry path that treated a non-retryable error as retryable. The fix comes as a before and after diff, tagged with the runtime evidence that justified it, and waits for a human.
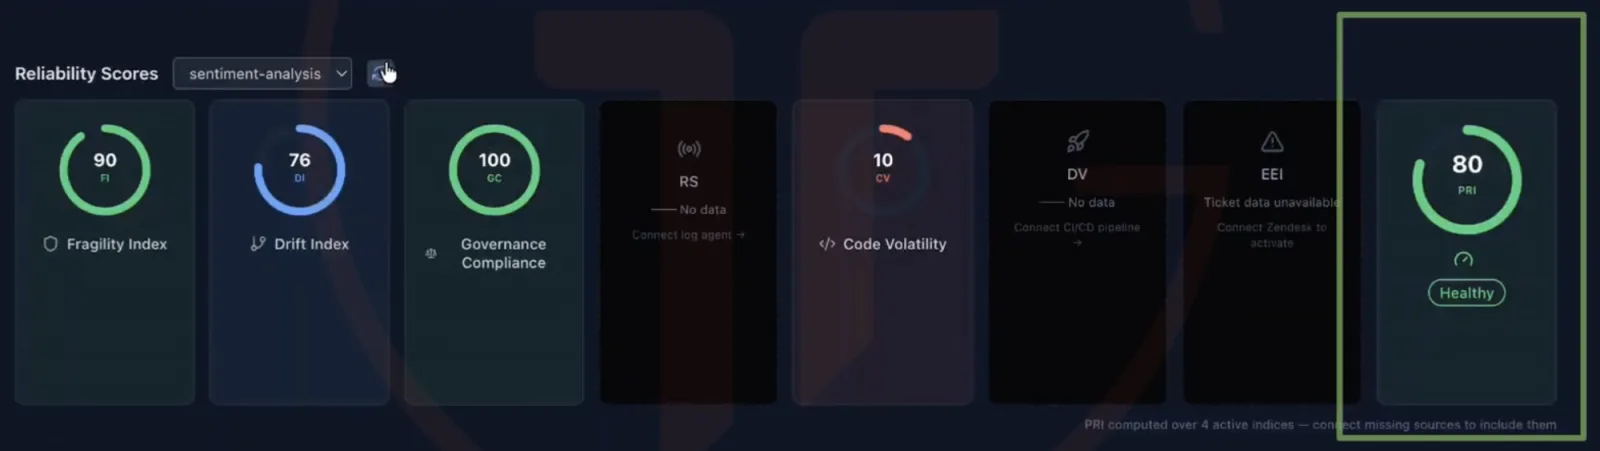
PRI 80, healthy — and this time the number carries production in it, drift included. The same loop runs tomorrow, on the next change and the next incident.