CodeRabbit runs a review workflow. A change comes in, the bot comments on it, and a person decides. Tomosu runs a reliability workflow. Your repository has a score, every change is scored against it, the merge is gated on the result, and production data feeds back into the score. The two connect over MCP, so most teams don’t have to pick one.
Free, no card. Repos over 50 files scan through the free VS Code plugin.
Tomosu is a production reliability tool for AI-written and human-written code. It answers a different question about the same pull request than CodeRabbit does.
- CodeRabbit asks whether a change is written well.
- Tomosu asks whether the system will still hold up once the change merges, scores the answer from 0 to 100 as a Production Reliability Index (PRI), and lets a merge gate act on it.
- If you want a line-by-line review, keep CodeRabbit and plug Tomosu into it.
Two workflows for the same pull request
The review workflow (CodeRabbit)
- A developer or coding agent opens a pull request.
- CodeRabbit reads the change, with context from the rest of the codebase and any linked repositories.
- It posts a summary and line-by-line comments, and can suggest or apply fixes.
- A person reads the comments and decides whether to merge.
The output is advice. It works when someone reads it, and the merge decision stays with whoever presses the button.
The reliability workflow (Tomosu)
- Tomosu scans the whole repository and gives it a PRI from 0 to 100, broken into eight sub-indexes.
- While the change is being written, the VS Code plugin and the MCP server show how it moves that score, to you and to your coding agent.
- When the pull request opens, the GitHub App posts the score change on it.
- If the score is under the threshold you set, the Tomosu Git Agent won’t open or auto-merge the pull request.
- On the Team plan, production logs, metrics and traces from a runner inside your network feed back into the score.
The output is a number with findings behind it, and the rule for acting on it is set before anyone looks at the change.
How the two workflows connect over MCP
CodeRabbit can call Tomosu’s MCP server during a review, so the reliability score lands in the same pull request thread as the review comments. Coding agents can call the same server while they write the change, which means the agent sees the score before any reviewer, human or bot, does.
To connect them, open Review in CodeRabbit, then Integrations, then the MCP Servers tab. Add the Tomosu MCP server URL, pick OAuth, sign in with the Google account tied to Tomosu, and enable all 8 tools. One person sets it up for the whole CodeRabbit org. Full setup guide
What the reliability workflow adds
What a reliability finding looks like
These are blind scans of real open source bugs, with the success criterion fixed before each scan.
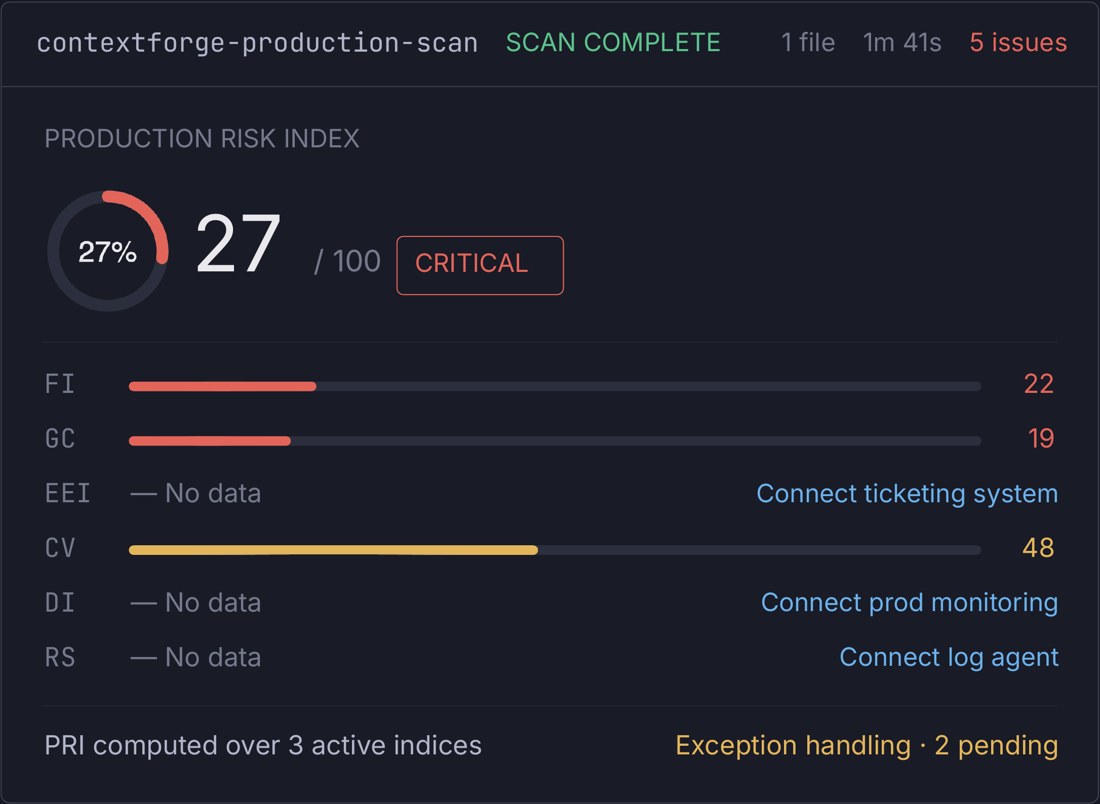
- IBM ContextForge. The pre-fix
token_scoping.pyscored PRI 27 out of 100. The scan flagged the unsafe session cleanup behind PostgreSQL connections sitting “idle in transaction” until the pool ran out. Read the case study - Celery. The pre-fix
events/state.pyscored PRI 30 out of 100. The scan found the unbounded memory growth first reported in 2018 and recommended a bound that matches the one maintainers shipped in 2026. Read the case study - Prefect. Given only a traceback, Tomosu named the file, function and root cause of a negative-timeout crash in
pause_flow_run, and the case study lists the one thing it missed. Read the case study
What the reliability workflow checks
The pre-merge rules cover about 59 categories. Most of the weight sits on the failures that page on-call engineers:
- concurrency safety, the largest group
- database performance and transaction boundaries
- error handling, including swallowed and misclassified failures
- connections, streams and handles that are never released
- timeouts, retries, backoff, and whether a circuit breaker exists
- async messaging: ordering, duplicate delivery, poison messages
An LLM proposes candidate findings. A fixed scoring matrix of 375 pre-merge rules and 265 runtime rules decides what counts, with weights applied in Tomosu’s own code. Rules that need history the scanner can’t see, such as incidents, alerts or git history, are switched off on a code-only scan instead of guessed.
Because the score covers the whole repository, a change that looks clean in its own diff can still lower it: a connection that is opened and never released, a retry loop with no backoff, a transaction that now wraps a network call. More on this in Production Reliability vs Code Review and What a Repository-Wide Review Finds That a PR Diff Misses.
How the merge gate works
You set one threshold. If nobody sets it, it’s 40 out of 100. When the Tomosu Git Agent opens or merges a GitHub pull request or a GitLab merge request, it checks the branch score first. Below the threshold, the call is refused with a 422 that carries the score, the threshold and the reason.
On GitHub, before an auto-merge the agent also checks commit status, test and CI check runs, at least one approving review, no conflicts, and that the branch isn’t behind. Each check is a toggle, so the review workflow and the reliability score can both have to pass before anything merges. On GitLab the score is the check the agent adds; the rest is left to GitLab’s own merge rules.
The gate sits on Tomosu’s own write path, so a merge done directly in GitHub’s or GitLab’s UI goes around it. And if Tomosu’s scoring service is unreachable, the action goes ahead, because a reliability tool that takes your pipeline down during its own outage has failed at its one job.
PR gates start on Starter, and the Git Agent with the PRI merge gate is on Team.
The two workflows side by side
| Review workflow: CodeRabbit | Reliability workflow: Tomosu | |
|---|---|---|
| Question it answers | Is this change written well? | Will the system hold up after it merges? |
| Unit of work | The pull request, with codebase and linked-repo context | The repository, then each change against it |
| Output | Summaries, line-by-line comments, suggested fixes | A 0 to 100 PRI with eight sub-indexes and findings by category |
| Who decides the merge | A person reading the review, plus any pre-merge checks you configure | A threshold set in advance (default 40/100), checked by the Git Agent |
| Where you see it | Pull request, CLI, IDE | VS Code plugin, coding agent via MCP, pull request, VisionBoard |
| Production signals | CI results, such as failed Jenkins builds | Logs, metrics and traces through a runner in your network (Team and Govern) |
| Git hosts | GitHub, GitLab, Azure DevOps, Bitbucket | GitHub, GitLab |
| Pricing model | Per user: $24, $48 or $72 a month; Enterprise custom | Metered, no seats: Free (250 TCUs once), Starter $39/mo, Team $99/mo, Govern custom |
CodeRabbit details from CodeRabbit’s pricing page and docs, checked November 2, 2026.
How pricing compares
CodeRabbit charges per user, so a 10-person team on Essentials pays $240 a month at the monthly list price. Tomosu doesn’t count seats. It meters TCUs, roughly 34 KB of code read and analysed per unit, at ten cents each on paid plans. A large repo costs more than a small one no matter how many people work on it, and connecting repos or adding developers and agents uses no TCUs. See plans and pricing for the full breakdown.
Other CodeRabbit alternatives, by workflow
| Tool | Workflow | Pick it if |
|---|---|---|
| Greptile | Review | Your codebase is large or tangled and reviews need repository-wide context. Works on GitHub and GitLab. |
| GitHub Copilot code review | Review | You’re on GitHub and want review without adding a vendor. |
| Qodo / PR-Agent | Review | You want an open source reviewer you can self-host. |
| Cursor Bugbot | Review | Your team already writes code in Cursor. |
| SonarQube | Static analysis gate | You want deterministic rule checks with quality gates that fail the build. |
| Tomosu | Reliability gate | You want a production reliability score for the repository and each change, a merge gate on it, and runtime evidence feeding it. |
When the review workflow is all you need
Tomosu isn’t the right tool in four cases, and it’s better you hear that from us.
Security and your code
- Your code is never used to train models.
- Read-only scopes. The runtime runner dials out, so there are no inbound ports and no agent on production hosts.
- Secrets are filtered before anything leaves your network.
- Per-customer isolation, with retention and deletion set by you.
- Self-hosted runners, dedicated tenancy and data residency on Govern.
Tomosu runs a written information security program designed in alignment with SOC 2 Type II and ISO/IEC 27001. Ask us for current certification status.
Languages: Python, JavaScript and TypeScript (including JSX and TSX), Java (including JSP and JSF), C#, Ruby, Scala, Rust, Go, C, shell, Terraform, XML and config files.
FAQ
Is Tomosu a replacement for CodeRabbit?
They run different workflows. CodeRabbit reviews changes and leaves comments for a person to act on. Tomosu scores reliability and gates merges on that score. Teams that want both connect them over MCP, and CodeRabbit posts Tomosu’s score next to its own review.
What’s the difference between AI code review and a reliability gate?
AI code review produces comments for a person to read and act on. A reliability gate produces a score and a pass or fail rule that was set before the change arrived. CodeRabbit is AI code review. Tomosu is a reliability gate.
Is there a CodeRabbit alternative that checks production reliability instead of code style?
Yes. Tomosu scores code on how it will behave under production load, covering concurrency, resource leaks, timeouts and retries, database transactions and async messaging, and turns that into a 0 to 100 Production Reliability Index that a merge gate can check.
What tool can stop a pull request from merging if AI-generated code is likely to break production?
Tomosu’s Git Agent refuses to open or auto-merge a pull request when its reliability score is below your threshold. SonarQube quality gates do something similar for static analysis rules through branch protection. On the Team plan, Tomosu’s score also takes production logs, metrics and traces into account.
Can I run Tomosu and CodeRabbit together?
Yes. Add the Tomosu MCP server under CodeRabbit’s Integrations and CodeRabbit will post a Tomosu reliability comment alongside its own review.
Does Tomosu block merges on GitHub and GitLab?
Yes, on GitHub pull requests and GitLab merge requests opened or merged through the Tomosu Git Agent: it refuses them when the score is under your threshold. It doesn’t stop someone merging from GitHub’s or GitLab’s own UI, and it lets actions through if Tomosu is unreachable.
How much does Tomosu cost compared with CodeRabbit?
Tomosu has a free plan with 250 TCUs and no card, then Starter at $39 a month and Team at $99 a month, with no per-seat charge. CodeRabbit’s listed plans are $24, $48 and $72 per user per month.
Which languages and Git hosts does Tomosu support?
GitHub and GitLab. Python, JavaScript, TypeScript, Java, C#, Ruby, Scala, Rust, Go, C, shell and Terraform, among others. Not PHP, Kotlin, Swift or C++ yet.
Is my code used to train models?
No, never.
Add the reliability workflow to your repo
Run a free scan and get a PRI score with findings by category. If you already use CodeRabbit, one person can connect the two for the whole org.
Last checked against CodeRabbit’s public pages on November 2, 2026.